Your buyers ask AI who to pick. Make sure it’s you.
Gets you selected acrossChatGPTClaudeGeminiPerplexity
RocMode shows you whether AI picks you or your rival, finds the work that changes it, builds that work, and sends it to you to approve. Then it proves what moved.
We ask ChatGPT, Claude, Gemini and Perplexity the questions your buyers ask, and show where they pick you and who they pick instead. Free, no login. What’s the Score? Or sign up free and try everything for 14 days.
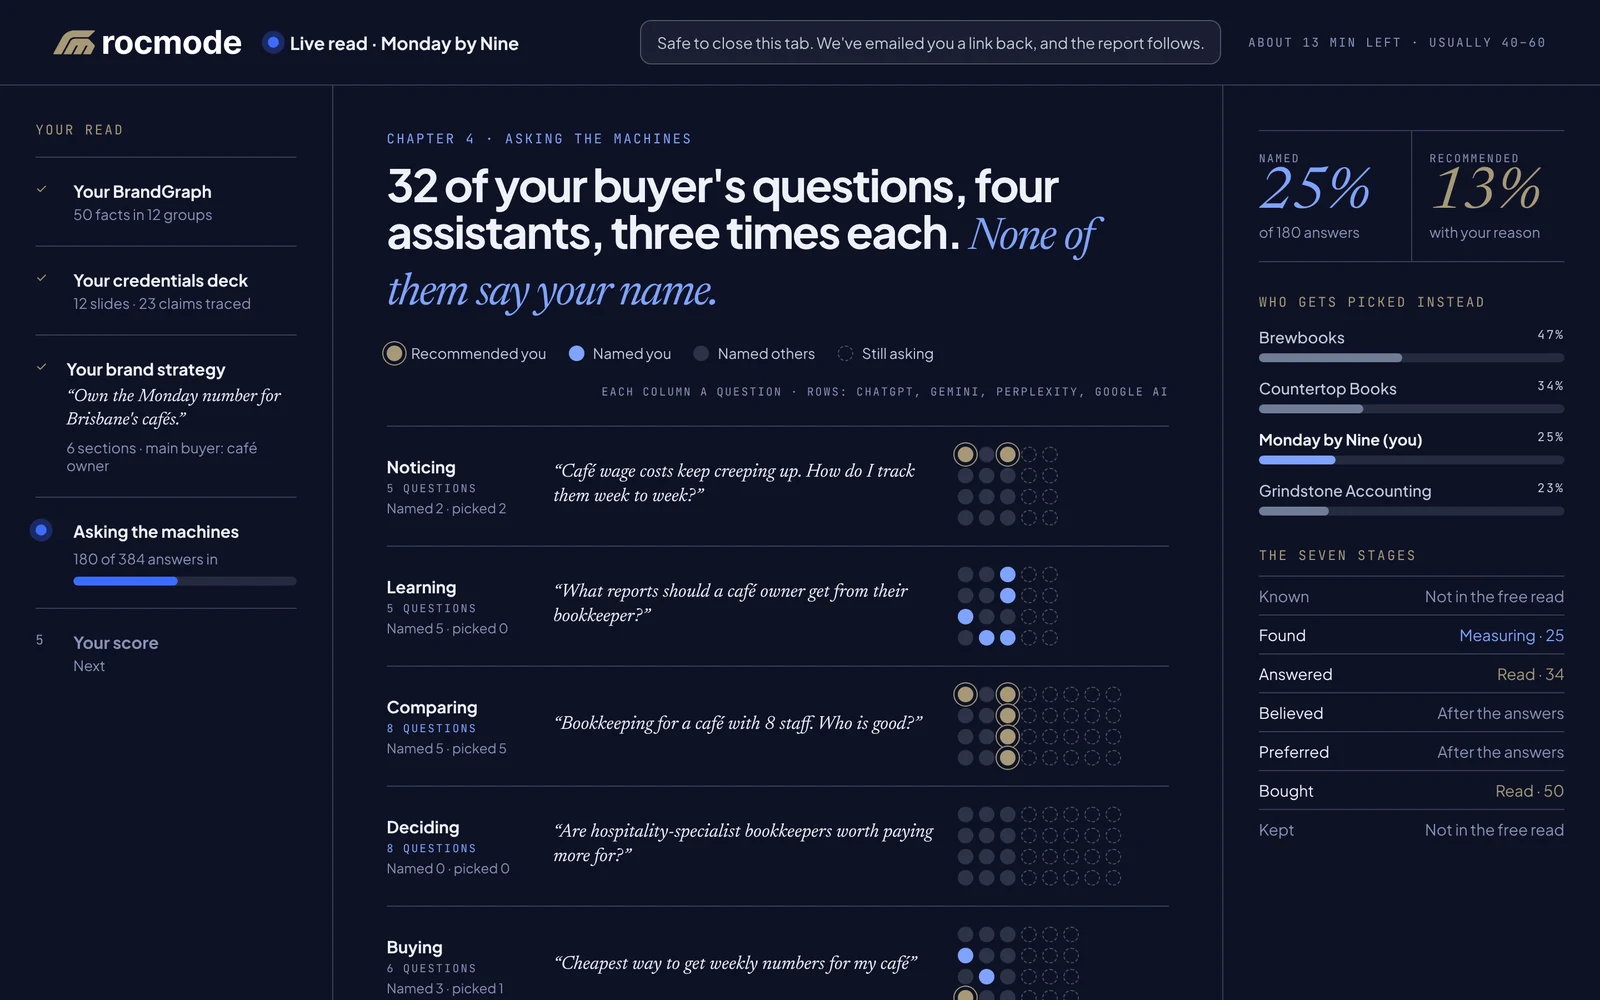
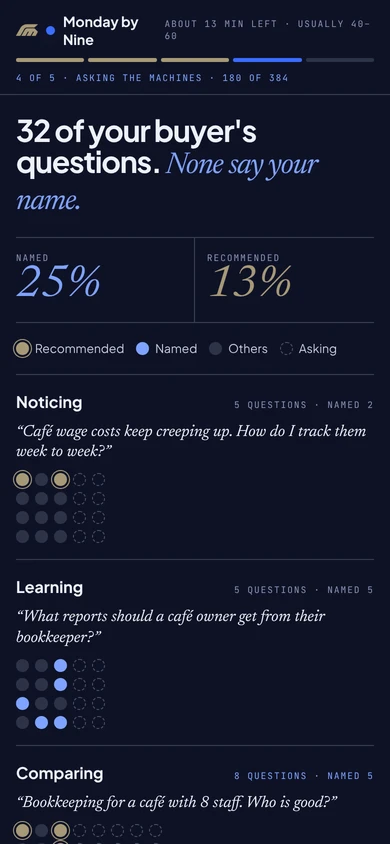
RocMode · Live read · Monday by Nine (example)
Asking ChatGPTBefore
The AI marketing and sales platform
Marketing and sales, rebuilt for the age of AI.
Your website in. A whole marketing and sales team’s work out. RocMode learns your brand from your site, then does the work: strategy, website, ads, social, PR, partners, email, design, and the deck that wins the deal. You approve every piece.
Other tools do one job. This does all of them, as one story.
Other AI guesses. This works from your facts and proof.
Other tools stop at the post. This follows it to the signed deal, and learns what won.
How it works
KnowWhere you really standActWhat to fix firstCreateWe build the work. You approve itProveDid it move?
Know · Step 1 of 10
It gets you. It gets your customers. It connects the dots.
Everything about your brand, your buyers and your rivals, sorted and connected.
Then it works out what to say, where, when and why. It’s the brain behind every step.
Builds: Customers · Offerings · Rivals · Proof
RocMode · BrandGraph · sample data
Following one momentCISO · Comparing · “Who’s the best managed security provider for a hospital group?”Moment found
Brand core3 found
Voice3 found
Visual identity3 found
Products and services3 found
Pricing3 found
Personas and markets3 found
Pains, gains, jobs3 found
Journeys and objections3 found
Proof and trust3 found
Content3 found
Competitors and partners3 found
Team2 found
Halvard Security35 facts
Two hospital case studies/partners
FactClaimProofAI-suggestedExample: Halvard Security, an invented managed security provider.
Reading halvardsecurity.com.au, socials, reviews and listings…
Halvard SecurityBrandGraph
12areas, all connected
3personas
15moments
6rivals
Sample data
Your customers
Customers
›
Personas
›
Journeys
›
Pains, jobs, objections
›
Moments
What you sell
Products and services
›
Offerings
›
Value proposition
›
Differentiation
Your rivals
Competitors
›
Industry
›
Expectations
›
Gaps to exploit
Moments + offerings
Opportunities
›
Campaigns
›
Ads
›
Sales
Content gaps
›
Content
›
Website
So it knows
What to say.Where. When. Why.
Moment foundCISO · Comparing · “Who’s the best managed security provider for a hospital group?”
Know · Step 2 of 10
Your strategy, from everything it knows.
Positioning built from your offerings and the gaps your rivals leave.
Claims you can’t back get cut before anyone sees them.
Seen isn’t selected. AI picks the brands it can tell apart.
Every era of marketing had its visibility number, and AI mentions are just the newest. Most AI tools still sell you visibility. But being mentioned isn’t being chosen, and for the first time you can measure the pick itself.
BroadcastAwareness
Media buyingReach
SearchRankings
SocialFollowers
AIMentions
What countsSelected
What AI made cheap
Making things.
Posts, pages, ads and reports in minutes
Anyone with a login can do it
Your competitors have the same tools
Sell on volume and you compete on price.
What AI made measurable
Being chosen.
Brand ABrand BYouBrand CBrand D
Buyers ask AI who to pick, and it names a few brands
You can ask the same questions and see who’s named
So you can see, moment by moment, where you win and lose
Compete on this and you compete on results.
See it on your brand
See how often AI picks you. Free.
We ask the AI assistants your buyers use the questions they really ask, many times each, at every step of their journey. Then we show where you’re picked, where you’re passed over, and who wins instead.
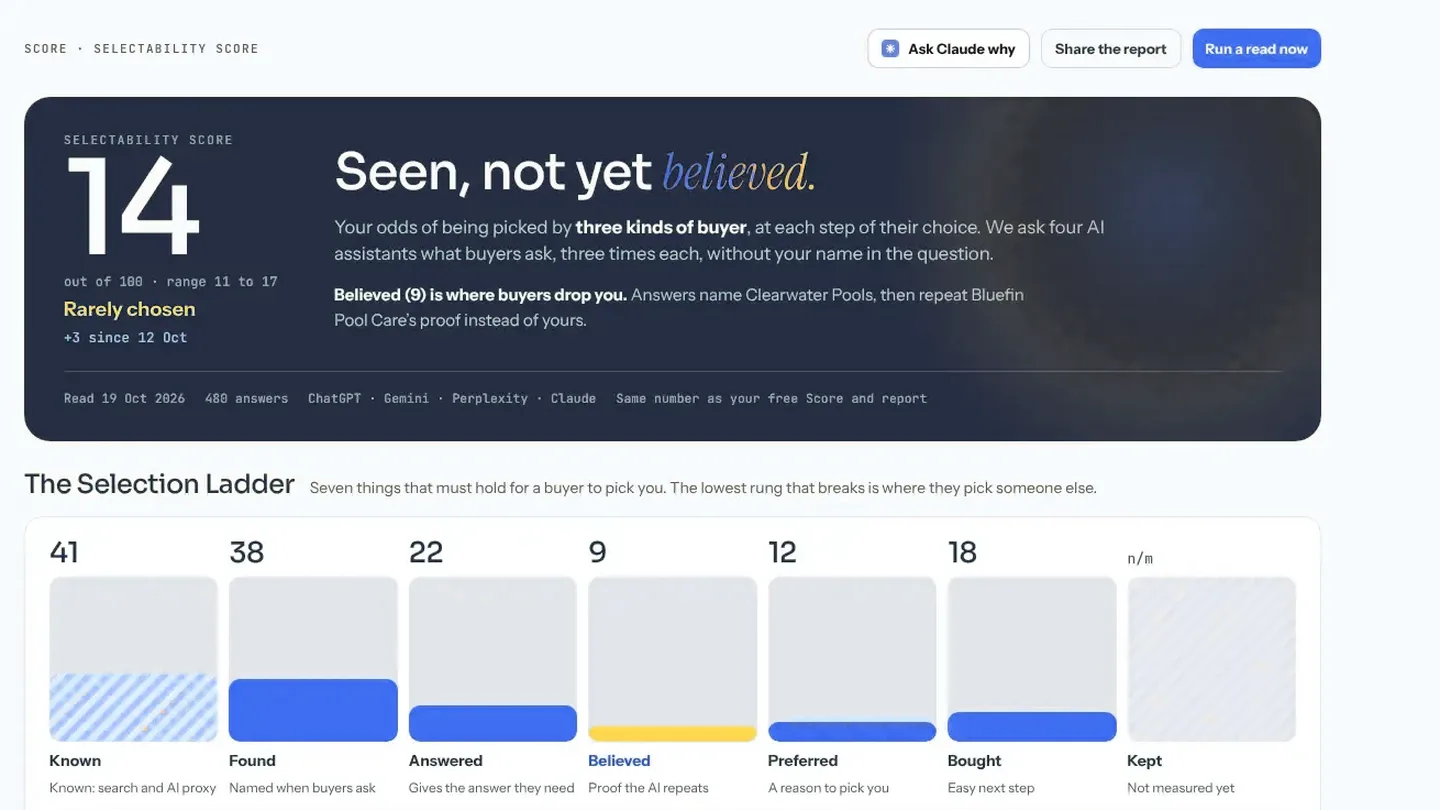
Your free Selectability Score asks the AI assistants the questions your buyers ask, without your name in them. You see who gets picked, at which moment, and the three gaps to fix first.
A reason counts only if it survives being repeated by someone else.
Evolut's first big win, in 2019, is still one of my favourites.
I can't remember exactly how we got to the table. We were brand new. I think our fresh new website did a pretty compelling job, and it ranked reasonably well, which can't have hurt.
We found ourselves pitching against two of Brisbane's larger digital agencies. I knew both well from the Cru Digital days. They were big and impressive. We were new and nimble.
So we pulled out all the stops. We met the client several times. We designed mock-ups. We thought hard about the strategy, the user experience, the structure of the site, the design and the pitch itself. Even by the standards I'd been used to at Cru, it was impressive work.
But that isn't what won her over. What won her over was us.
I'd brought together the best people from my old Cru and CXA teams: my best digital designer and my best CX strategist. Our new lead developer was hugely experienced too. We presented well, and the experience showed.
She told me afterwards, as I remember it: "I chose you because you were clearly senior and experienced. All three of you. You think clearly, and I can see myself running a project with you." Then she added that the pitch and the concept hadn't hurt our chances either, and that they'd helped win over her other stakeholders.
The project was worth several hundred thousand dollars, and it quickly put Evolut on the map.
Preferred is the stage where you aren't in the room. When you appear, are you the one recommended, and for a reason? The person or machine giving that reason is never you.
Most brands get this wrong because they write their reason for themselves. Then a customer, a colleague or an assistant tries to pass it on, and it falls apart or turns into "they're good".
People choose what they can defend
People pick the option they can justify, and they lean on that harder when someone else will hear the justification. That finding is decades old and well tested.
Eldar Shafir, Itamar Simonson and Amos Tversky reviewed the experiments in 1993. People, they wrote, "often seek and construct reasons" to settle a hard choice. They do it to "justify their choice, to themselves and to others" (Shafir, Simonson and Tversky).
Simonson had already tested the "to others" part (Simonson). Two known effects, compromise and attraction, push people towards the option that is easiest to explain. Both grew stronger when people expected to justify their choice to someone else. It's the closest lab test I know of the room you aren't in.
The counter-evidence. Richard Nisbett and Timothy Wilson showed that people often can't report why they chose (Nisbett and Wilson). Shoppers picked the right-most of identical stockings nearly four times as often as the left-most. "No subject spontaneously mentioned position." They praised the quality instead.
I accept that. The reason a buyer gives is often not the cause of the choice: the feeling picks, and the reason defends. That makes the reason more useful, not less. It's the currency of the choice, even when it isn't the cause. So leave the hidden cause alone. Your job is to supply a true reason that is easy to borrow.
I learned what that means from a loss. In 2020 a mining research organisation asked us to redesign its website. We sent a proposal within a fortnight and followed up for two months. When the answer came, it came with an apology: "You were actually still my preferred choice but I was overruled." The other agency had more examples from research and technology.
Our champion liked us. But "I liked them" doesn't survive a conversation with the boss. "They've done this for organisations like ours" does.
Three people who repeat your reason
Three re-tellers decide whether you're preferred: the machine, the champion and the customer. Each one has to say why, and none of them is you.
The machine has to say why. An assistant asked for a recommendation doesn't just name a brand. It gives a reason, and the reason shapes what the buyer does next.
A 2026 study tracked non-customers after an assistant mentioned a brand to them (Iannelli and Ai). Within seven days, a recommendation raised searches for the brand by 4.3 percentage points. A neutral mention raised them by 1.8 points. That's about 2.4 times the effect.
The panel size is withheld and the study is observational, so treat it as a strong hint.
Most brands sit in the weaker group. Leoprd looked at 31,200 answers about the brands it monitors (B&T). The brand was absent from 36%, "mentioned but not preferred" in 35%, and the primary recommendation in 29%. The full report isn't public.
The champion argues in a room you aren't in. In a business purchase, someone inside the buyer has to win over everyone else. CEB researchers, writing in HBR, analysed more than 700 business purchases (CEB in HBR). The contacts they called "Talkers" were four to six times less able to build consensus for a purchase.
Over 30% of those Talkers were senior executives, so a friendly, senior contact isn't enough. The CEB follow-up said suppliers must "arm them with the skills and materials needed to win over fellow decision makers" (HBR). Hand your champion a reason that travels.
The customer tells a friend. Fred Reichheld wrote that customers recommend only when they will "risk their reputations" (Reichheld). Whether his score predicts growth is contested, so I use only the mechanism. A recommendation spends the recommender's credibility, so they need a reason they can stand behind.
What gets repeated is also what gets cued. Jonah Berger and Eric Schwartz studied 335 word-of-mouth campaigns covering over 300 products (Berger and Schwartz). Interesting products got talked about at first, but not later. Products that everyday situations brought to mind kept being talked about. So a reason tied to a recurring moment travels further than a clever line.
One small firm shows the machine and the friend together. Tally, a ten-person company, makes online forms. Its onboarding survey found that "43% of new users discover Tally through ChatGPT, Claude, Gemini, Perplexity, and friends" (Tally, 22 September 2026).
Its reason is short: "Anyone can use Tally for free with unlimited forms and submissions" (Tally, June 2025). It credits years of answering questions in forums and communities, plus deliberate work on how AI describes it. The figures are self-reported, and whether assistants repeat the "free, unlimited" reason is untested.
To be someone's first choice, you must be wrong for someone else
A reason that suits everyone gives nobody anything to repeat. My working rule: if no sensible buyer would turn you down for it, it isn't a reason.
Roger Martin's opposite test still applies. State your claim, then its opposite. If the opposite is plainly stupid, every rival is saying the same thing.
This stage adds a second question. Who does your reason rule out, and would you say so out loud? A champion needs to be able to say "they're right for us because we are X". That only works if someone else isn't X.
This doesn't shrink your market. You rule out a reason, not the category's buyers. You still want every buyer in the category to know you, because growth comes from reaching them. The reason only has to win the ones whose situation it fits.
The counter-view. The Ehrenberg-Bass researchers argue that being distinctive matters more than being different. In their surveys across 17 categories, only 17% of a brand's users saw it as different or unique (Romaniuk, Sharp and Ehrenberg). Of Apple's users, 77% didn't see it as unique.
Those surveys measured established users, mostly in habitual categories, where nobody had to justify the choice to anyone. This chapter's claim applies where a third party has to explain it.
A reason doesn't have to be a specification. Vanguard's is an opinion: buy the whole market at low cost, rather than pick stocks. A survey for an advocacy group, Friends of Jack Bogle, asked investors to describe Bogle. A top phrase was "investing in the entire market with low cost index funds is better than stock picking" (Rockland Dutton survey). The sample wasn't disclosed and the sponsor was sympathetic. But it shows investors repeating the founder's reason, and a stock-picker would sensibly choose the opposite.
The reason gap
Every brand has three accounts of why it would be chosen: its own, its customers' and the machine's. Where they differ is the work. I call that difference the reason gap.
Your account is what you would say if asked "why you?". It's the most polished, and the least repeated. Your customers' account is what they say to a friend: rougher, often truer, and what they'll repeat. The machine's account is what an assistant says when it recommends you, or says about a rival when it doesn't. It's built from what other people wrote.
Line the three up and one of four things is true.
All three match. Rare. Keep checking.
Customers and machine agree, and you differ. They have found your real reason. Change your claim to fit it.
You and customers agree, and the machine differs. The reason exists, but not where the machine reads. Fix the sources.
All three differ. You have no reason that travels yet. Start with Chapter 11.
How to tell it is failing
An assistant names you, then recommends a rival first, or recommends nobody.
When it does recommend you, the reason is generic: "well reviewed", "popular", "good value".
Ten customers give ten different reasons, and none of them is yours.
A champion asks you for "something I can send to finance", then rewrites it.
Your reason, read aloud, could be on any rival's home page.
The method: the "why them?" test and the reason gap sheet
The "why them?" test collects the three accounts, lines them up on one sheet, closes the biggest gap and asks again. Run it once per moment.
Write your own account first. Finish "choose us when" in one sentence. Add the proof and who it rules out. Do this before you hear anyone else.
Run the opposite test. If a sensible rival wouldn't choose the opposite, rewrite before going further.
Collect the customers' account. Ask ten recent customers how they would describe you to a friend, what they would say if asked "why them?", and who they would not send to you. Write their words down exactly. Don't tidy them. Ten is a sample for spotting a pattern, not a rate, so report it as "n of 10".
Collect the machine's account. Run your buyers' unbranded questions through several assistants, several times each. Collect at least 20 answers per moment, the minimum, which still carries a margin of about 22 points either way. Note whether you were absent, named or recommended, and the reason given.
Add the champion (owner-led and committee sales only). Send a buyer contact one paragraph. Ask them to forward it to their finance lead, partner or accountant unedited. Ask what came back.
Score each account against yours. Use the scale below. Your reason-match is the number of customer answers, and the share of AI answers, that score 2 or 3. Keep the two apart.
Close the biggest gap at its source. If customers say something truer, change your claim. If the machine is vague, fix what it reads. If customers lack the words, give them a line and a moment to use it.
Retest. Same questions, new customers, after each change. Watch the recommendation rate and the reason-match together.
Score
What the account says
0
No reason, or one every rival could claim
1
A real reason, but not yours
2
Your reason, in other words
3
Your reason, with your proof
This scale is my own working rule, not tested against sales.
What makes a reason easy to repeat
A reason travels when it's short, specific and tied to a situation. My checks, drawn from the evidence above:
Can it be said in one breath? Tally's fits on one line.
Is there a moment that brings it to mind? Cued products kept being talked about.
Would it defend the choice if things went wrong? That is what Shafir and Simonson's subjects reached for.
Does it carry its proof, without your jargon? A number, a name or a result someone else can check, in words that aren't your product names.
The bookkeeper's reason gap sheet
The bookkeeper for cafés is an invented example. Her offer: "Bookkeeping for cafés. Your wage cost against takings, every Monday by nine." The answers below are invented too.
Account
What it says
Score
Hers
Bookkeeping for cafés. Your wage cost against takings, every Monday by nine
—
Customers (10 asked)
Six said "I get my numbers every Monday". Three said "she only does cafés". One said "she's nice"
Six at 2, three at 1, one at 0
The machine (20 answers to "bookkeeper for a café")
Named in 4. Described as "a bookkeeper for small hospitality businesses"
1 where named
Reason-match
Answers scoring 2 or 3
6 of 10 customers; 0 of 20 AI answers
The customers have her reason, roughly. They say "Monday" but drop "wage cost against takings", the part that makes her worth choosing. So her Monday email now opens with "This week, wages were X% of takings".
The machine's gap is bigger. Nowhere it reads says "Monday" or "wages". So she publishes the twelve-month case as a page, asks every client for a review at the end of their first quarter, and reruns the same questions a month later.
Fieldline's reason gap sheet
Fieldline, the invented scheduling-software firm, is still working on Northgate Heating & Cooling. By now Mei's integration questions are answered and Ravi's travel-time contradiction is fixed. One person is left: the owner-CEO, who signs.
Account
What it says
Score
Fieldline's
Cuts your technicians' travel time, proven in a 2023 pilot
—
Customers (10 asked)
Seven ops leads: "the dispatchers love the map". Two finance leads: "it replaced two other tools". One: "less driving"
1 of 10 at 2
Dana, to the CEO
"It's the best scheduling tool we looked at"
0
The machine (20 answers)
"A well-reviewed scheduling tool with a strong mobile app"
0 of 20 at 2 or 3
Dana, Northgate's head of operations, is the champion. She wants Fieldline. The CEO asks her one question in the corridor: "Why Fieldline?"
She reaches for the line she has: "It's the best scheduling tool we looked at." "They all say that," he says, and the decision slides to next month's meeting.
That's the reason gap in one sentence. Dana had a reason and a mood, and she could only repeat the mood.
So Fieldline's account manager asks Dana the customer questions, turned round: "How would you explain it to him?" Dana talks about her eighty technicians. "Half of them spend a day a week in the van between jobs."
Fieldline rewrites its claim to pass the opposite test. "Choose Fieldline when travel, not paperwork, is what eats your technicians' day." A sensible rival chooses paperwork, and says so. It rules out in-house facilities teams whose staff never leave one site.
Then it hands the reason back in Dana's words. Her version for the CEO reads: "We pay eighty people to sit in vans for a day a week. Fieldline is built to cut that, and its pilot shows by how much." Fieldline also publishes the 2023 pilot where the machine can read it.
At the next meeting the CEO didn't say "they all say that". He asked, "And what does it cost us if it doesn't work?" That is a reason surviving the room. His new question belongs to the next stage.
By mode
In habitual categories almost nobody has to repeat a reason, so a look and a name people know carry more weight. For a quick choice, the machine has to lift your reason whole, in one line. In a considered personal purchase, the buyer has to repeat it to a partner or friend. An owner has to repeat it to a partner, an accountant or staff, so give them "for a business like yours", with proof from one like theirs. In a committee, the champion needs one forwardable paragraph per role. This is my reading of the evidence, like the other mode summaries.
How Preferred connects to the other stages
It needs a reason and one truth. State the reason three ways and the machine picks one.
It needs proof. A reason with no proof is a judgement, and nobody accepts a judgement from the party who gains from it.
It feeds Bought and Kept. The landing page has to repeat the reason, and at renewal the buyer asks whether it still holds.
What not to do
Don't chase the top slot. Iannelli and Ai found it was "being named at all, not where in the list" that moved behaviour. Earn the reason instead.
Don't pay for a reason, or rewrite your pages for one model. Write for the question, and retest across assistants.
How you know it worked
The Selectability Score (Part five) checks Preferred with one question. When you appear, are you the one recommended, with a reason? It scores how strongly you're recommended, and whether your reason is the one given.
Your own numbers:
Recommendation rate. Of at least 20 unbranded answers per moment, the share where you're the first choice.
Reason-match. The share of AI answers that give your reason, scoring 2 or 3, reported apart from the customer count.
Customer retell. Out of ten recent customers, how many say your reason unprompted. Report it as "n of 10", never as a percentage.
Forward test. Whether your champion's paragraph comes back with a question, not a rewrite.
This afternoon
ask one assistant to recommend a supplier like you, without naming yourself, five times. Write down the reason it gives each time. Then write your own in one sentence, and see whether any of the five match.
This quarter
run the full "why them?" test on your most valuable moment, close the biggest gap at its source, and retest.
Toolkit
The "why them?" test. Use it once a quarter per moment, and after any change to your claim. Collect the three accounts, compare them, close the gap and retest.
Read it left to right, then follow the loop from "Retest" back to "Compare them", because the test never finishes.
Every template for this stage is in the free Selectability Playbooks at rocmode.com/playbooks.
What we don't know
No study links a retold reason to win rate. The thesis is my inference from work on reasons, champions and word of mouth. Nobody has tested it end to end.
Whether assistants repeat a brand's own reason. I found no independent record of assistants giving Tally's or Vanguard's stated reason.
How much the machine evidence holds. Iannelli and Ai and Leoprd have undisclosed panels or unpublished reports.
Whether the machine's stated reason is its real one. People give reasons that aren't causes. The reason gap may measure what's said more than what decides.
Whose evidence this is. Iannelli and Ai both work for Scrunch AI, which sells AI visibility tools. Leoprd is an AI visibility and reputation advisory. CEB, now part of Gartner, sells sales advice. Reichheld went on to sell Net Promoter, and the Ehrenberg-Bass Institute sells research to sponsor brands. Tally's figures are its own. Peer-reviewed sources: Shafir, Simonson and Tversky; Simonson; Nisbett and Wilson; Berger and Schwartz.