Your buyers ask AI who to pick. Make sure it’s you.
Gets you selected acrossChatGPTClaudeGeminiPerplexity
RocMode shows you whether AI picks you or your rival, finds the work that changes it, builds that work, and sends it to you to approve. Then it proves what moved.
We ask ChatGPT, Claude, Gemini and Perplexity the questions your buyers ask, and show where they pick you and who they pick instead. Free, no login. What’s the Score? Or sign up free and try everything for 14 days.
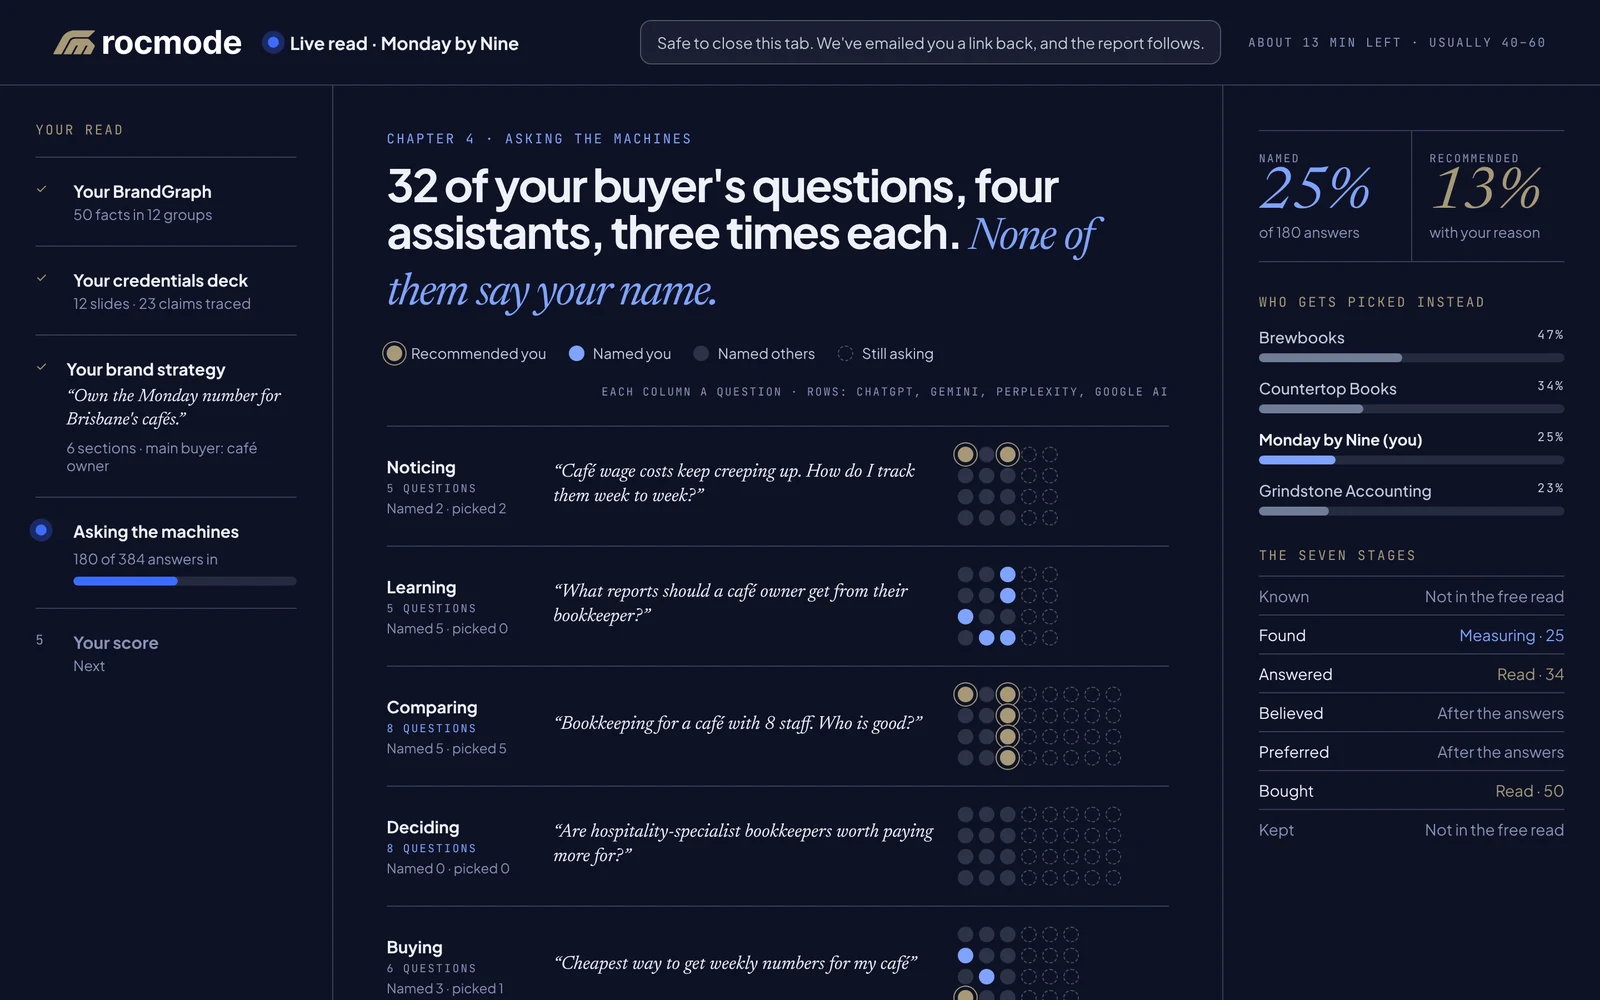
RocMode · Live read · Monday by Nine (example)
Asking ChatGPTBefore
The AI marketing and sales platform
Marketing and sales, rebuilt for the age of AI.
Your website in. A whole marketing and sales team’s work out. RocMode learns your brand from your site, then does the work: strategy, website, ads, social, PR, partners, email, design, and the deck that wins the deal. You approve every piece.
Other tools do one job. This does all of them, as one story.
Other AI guesses. This works from your facts and proof.
Other tools stop at the post. This follows it to the signed deal, and learns what won.
How it works
KnowWhere you really standActWhat to fix firstCreateWe build the work. You approve itProveDid it move?
Know · Step 1 of 10
It gets you. It gets your customers. It connects the dots.
Everything about your brand, your buyers and your rivals, sorted and connected.
Then it works out what to say, where, when and why. It’s the brain behind every step.
Builds: Customers · Offerings · Rivals · Proof
RocMode · BrandGraph · sample data
Following one momentCISO · Comparing · “Who’s the best managed security provider for a hospital group?”Moment found
Brand core3 found
Voice3 found
Visual identity3 found
Products and services3 found
Pricing3 found
Personas and markets3 found
Pains, gains, jobs3 found
Journeys and objections3 found
Proof and trust3 found
Content3 found
Competitors and partners3 found
Team2 found
Halvard Security35 facts
Two hospital case studies/partners
FactClaimProofAI-suggestedExample: Halvard Security, an invented managed security provider.
Reading halvardsecurity.com.au, socials, reviews and listings…
Halvard SecurityBrandGraph
12areas, all connected
3personas
15moments
6rivals
Sample data
Your customers
Customers
›
Personas
›
Journeys
›
Pains, jobs, objections
›
Moments
What you sell
Products and services
›
Offerings
›
Value proposition
›
Differentiation
Your rivals
Competitors
›
Industry
›
Expectations
›
Gaps to exploit
Moments + offerings
Opportunities
›
Campaigns
›
Ads
›
Sales
Content gaps
›
Content
›
Website
So it knows
What to say.Where. When. Why.
Moment foundCISO · Comparing · “Who’s the best managed security provider for a hospital group?”
Know · Step 2 of 10
Your strategy, from everything it knows.
Positioning built from your offerings and the gaps your rivals leave.
Claims you can’t back get cut before anyone sees them.
Seen isn’t selected. AI picks the brands it can tell apart.
Every era of marketing had its visibility number, and AI mentions are just the newest. Most AI tools still sell you visibility. But being mentioned isn’t being chosen, and for the first time you can measure the pick itself.
BroadcastAwareness
Media buyingReach
SearchRankings
SocialFollowers
AIMentions
What countsSelected
What AI made cheap
Making things.
Posts, pages, ads and reports in minutes
Anyone with a login can do it
Your competitors have the same tools
Sell on volume and you compete on price.
What AI made measurable
Being chosen.
Brand ABrand BYouBrand CBrand D
Buyers ask AI who to pick, and it names a few brands
You can ask the same questions and see who’s named
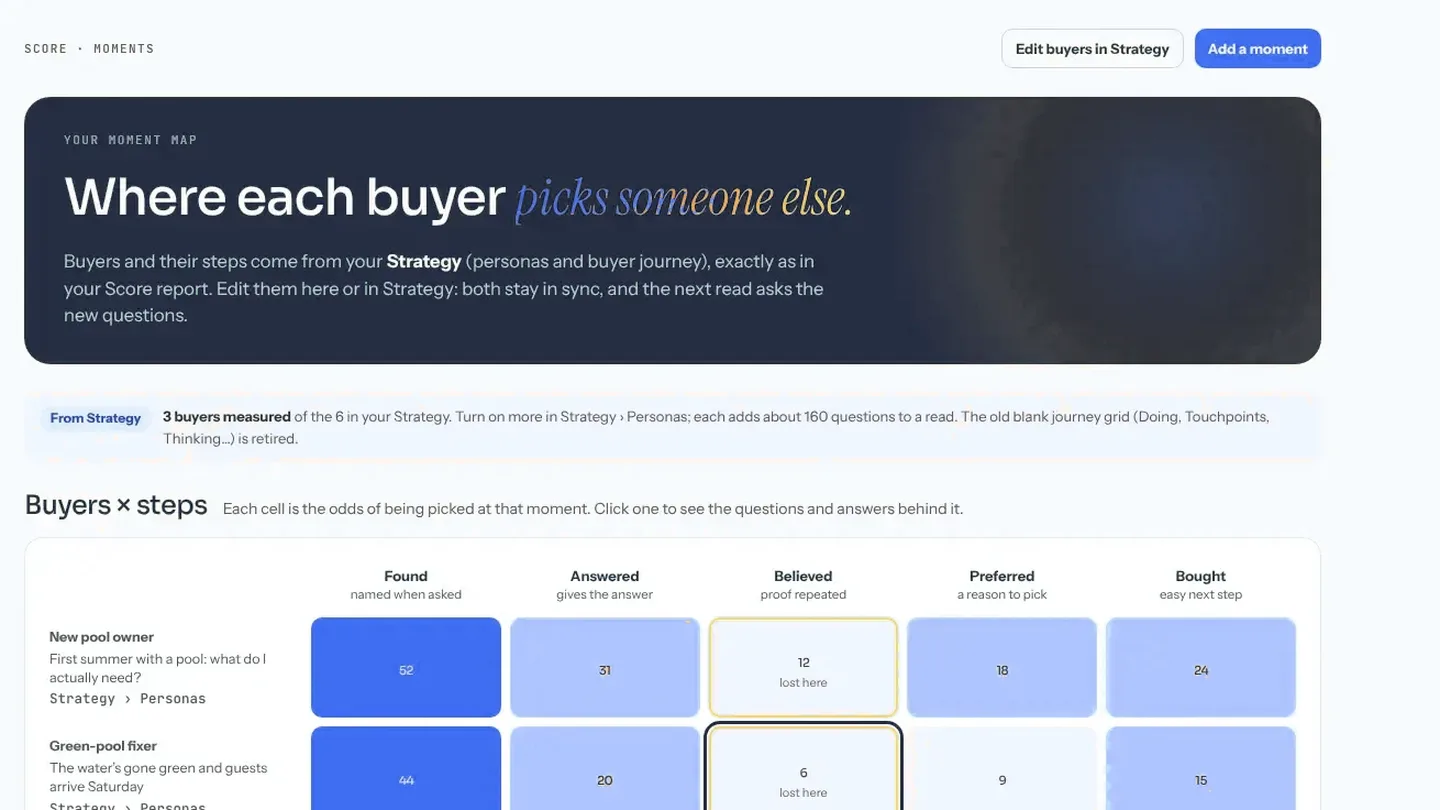
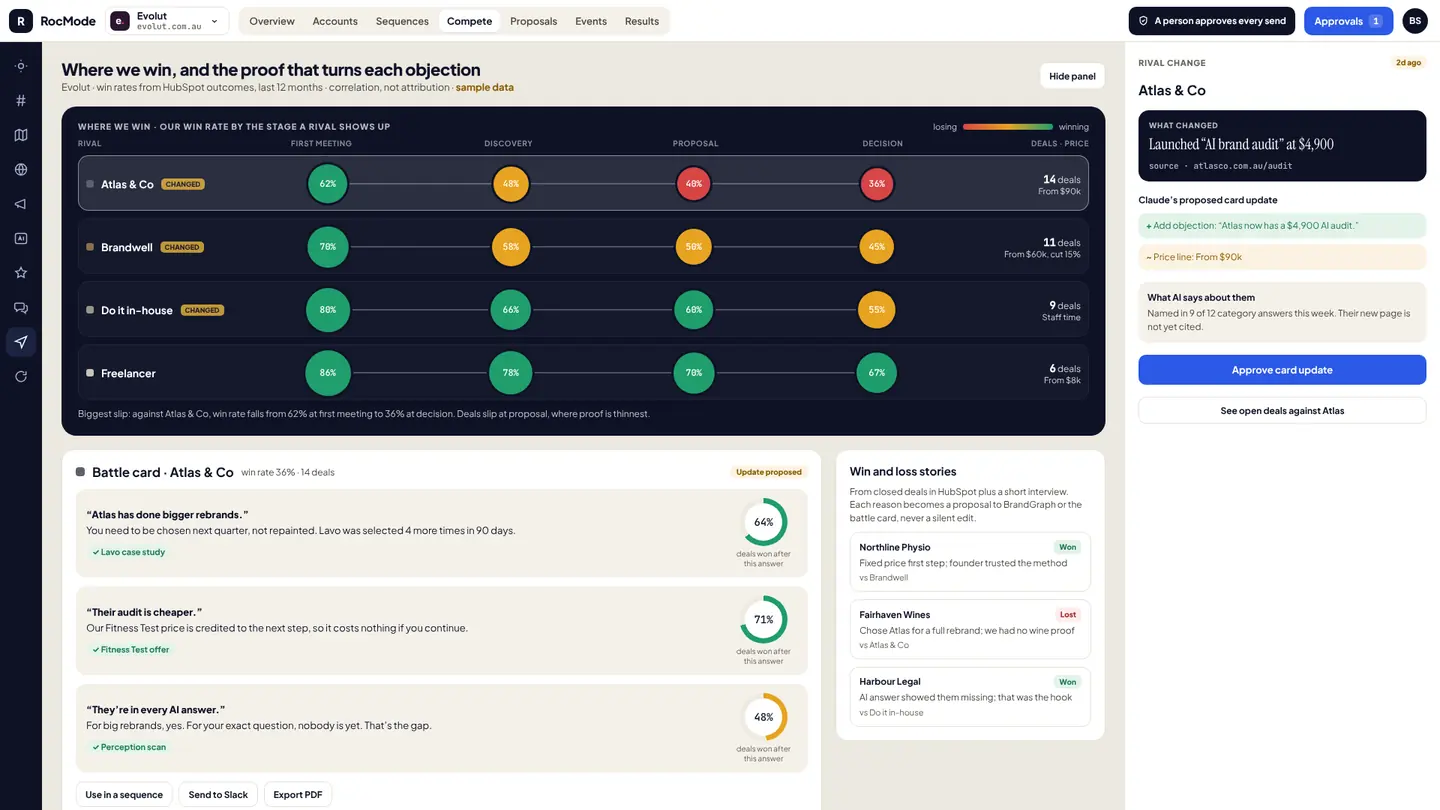
So you can see, moment by moment, where you win and lose
Compete on this and you compete on results.
See it on your brand
See how often AI picks you. Free.
We ask the AI assistants your buyers use the questions they really ask, many times each, at every step of their journey. Then we show where you’re picked, where you’re passed over, and who wins instead.
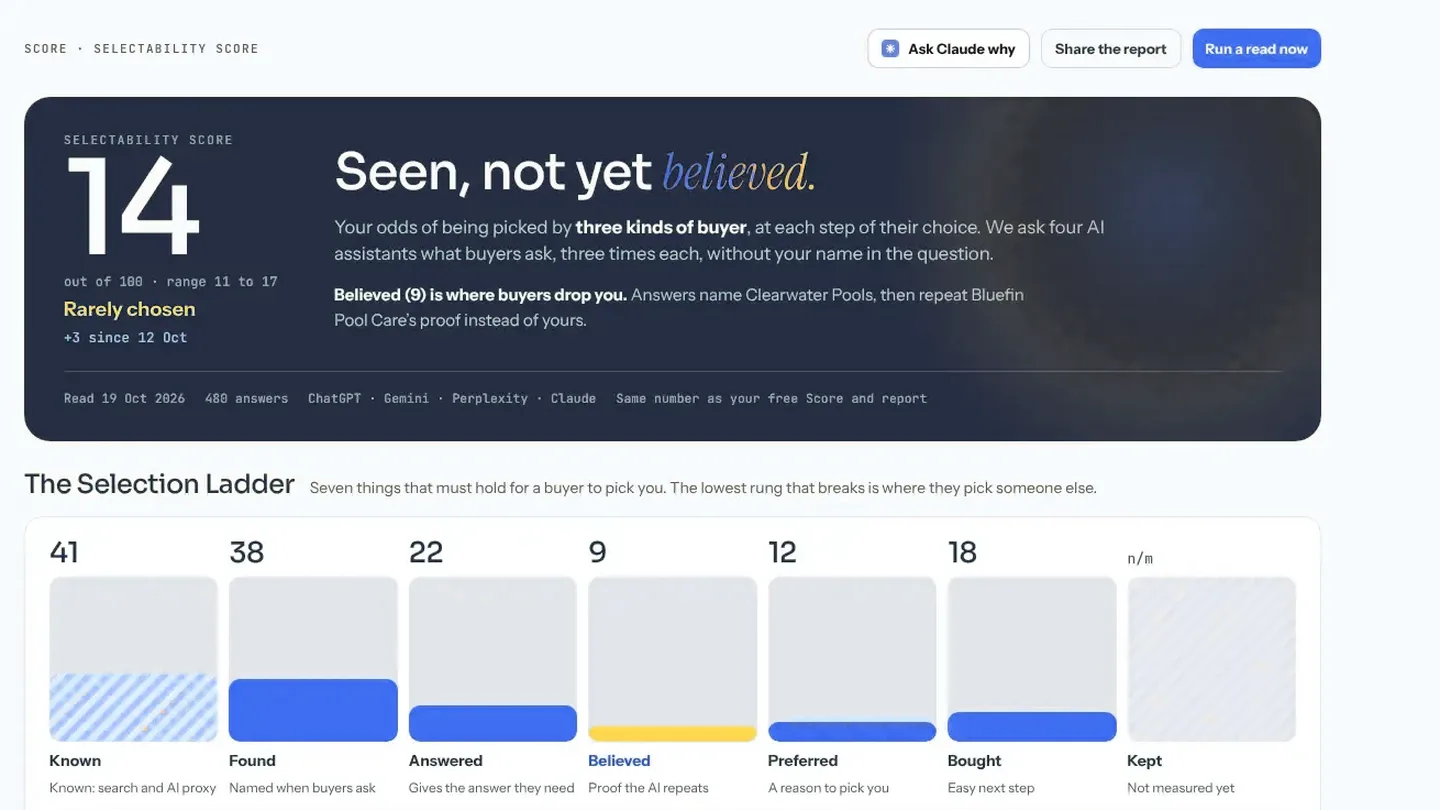
Your free Selectability Score asks the AI assistants the questions your buyers ask, without your name in them. You see who gets picked, at which moment, and the three gaps to fix first.
You can't claim belief. You can only supply the evidence for it.
At Cru Digital, most of our work came from our work.
Our own website did more selling than any of us. It didn't look like every other corporate site, and prospects drew their own conclusion: if we could build something that bold, we could certainly build theirs. Years later I put it to a colleague plainly. I was convinced we'd won most of our work because of the website we had.
The next most common reason was a small line at the bottom of somebody else's website: "Site by Cru Digital". We believed in our craft completely, and every site we built carried the proof to whoever visited it.
Most of the rest came through referrals, and there were a lot of them. Clients had a good experience with us, and when someone asked who'd built their site, they told them.
Evolut is a much smaller agency, but the pattern hasn't changed. Almost all of our work still comes from referrals.
Which is exactly why an AI assistant had never heard of us. A recommendation over coffee is powerful, but it leaves nothing behind for a machine to read.
Believed is the stage where your own words count for least. A buyer, and now a machine, weighs what you say against what everyone else says. Where the two differ, they go with everyone else.
Belief comes from two things: proof the buyer can check, and voices that aren't yours. And you have to say the same thing everywhere, because the machine won't catch your contradictions. It will repeat them.
Two kinds of claim
Facts are things only you can say with authority: your price, your hours, your terms, what the product does, who you serve. Buyers want these from you, and they want them stated the same way everywhere.
Judgements are what you would like buyers to conclude: that you're reliable, fast, easy to deal with, the best choice. Nobody accepts a judgement from the party who gains from it.
The evidence splits the same way. In Nielsen's 2015 survey across 60 countries, 70% trusted brands' own websites, slightly more than online reviews. Recommendations from people they know led, at 83%, and 88% in 2021 (Nielsen). This is stated trust, and the figures are dated.
The machines seem to split the same way. McKinsey reported in 2026 that only 1% of the sources AI models cite on consumer goods are brands' own websites (McKinsey). Yext analysed 6.8 million citations and put brand websites at 44% (Yext).
My interpretation, not a tested finding, is that they answer two different questions. Yext's questions were local and practical, such as opening hours. Those are facts, and the machine went to the brand. "Which is best" asks for a judgement, and the machine went to everyone else. Neither study publishes its full method.
The pattern is the chapter in one line. On facts, the buyer and the machine read you. On judgements, they read others.
Your lawyers know the first half. In the US, advertisers must have "a reasonable basis" for objective claims before they run (FTC). In the UK, marketers must "hold documentary evidence" for them (CAP Code). So legal often holds a ready-made proof file. Start there, and give the inventory one owner across every product line.
One contradiction anywhere can be repeated everywhere
It would be convenient if the machine caught your contradictions. It mostly doesn't, and that's worse.
IBM's team found that "all models struggle" to reflect a conflict between two passages, especially when it's implied rather than stated (Hou and colleagues). A Stanford team found models took wrong retrieved information over their own correct knowledge more than 60% of the time (Wu, Wu and Zou).
So the machine doesn't referee your inconsistencies. It picks one version, often whichever is most relevant to the question, and states it with confidence. If your pricing page says one thing and an old listing says another, the buyer may be told either.
Air Canada learned what that costs. Its website chatbot told a grieving customer he could claim a bereavement fare after travelling. The policy page on the same website said he couldn't.
A Canadian tribunal ruled that the chatbot was "still just a part of Air Canada's website". A customer couldn't be expected to check one part of the site against another (Moffatt v. Air Canada). The damages were about C$650. The coverage went around the world.
People react differently. When a source sends mixed signals, they start checking the argument (Ziegler, Diehl and Ruther). So the machine repeats whichever version it finds, and the buyer who checks finds the other one. Only the brand that says one thing everywhere is safe.
Why other people count more
A source that gains from your belief is discounted, and one that gains nothing isn't.
Martin Eisend and Franziska Küster combined the published experiments comparing editorial coverage with advertising. Coverage's lead on credibility was about three times its lead on how the message itself was rated (Eisend and Küster).
There's a real limit, and it matters to large brands. Coverage won for unfamiliar products, but for established brands advertising did better. A famous brand borrows belief from familiarity, so this chapter's case is strongest for challengers.
Reviews show the same thing in behaviour. Northwestern's Spiegel Research Center studied clickstream data from a handful of retailers (Spiegel). Four findings are worth knowing:
A product with five reviews was 270% more likely to be bought than one with none.
Displaying reviews lifted conversion by 190% for cheaper items and 380% for dearer ones.
Reviews from verified buyers lifted purchase likelihood by 15% over anonymous ones.
Purchase likelihood peaked at an average rating of about 4.2 to 4.7, and fell towards a perfect 5.0.
The data is from 2017, and the direction hasn't been seriously challenged since.
Small firms gain most. Michael Luca of Harvard Business School matched Yelp ratings with Washington State tax records for restaurants. "A one-star increase in Yelp rating leads to a 5-9 percent increase in revenue", and the effect was "driven by independent restaurants" (Luca). Chains saw no effect, and lost market share as Yelp spread. Other people's words did for the independents what a famous name does for a chain.
The machines lean on other people too, but on no single source. Profound analysed 680 million citations, and the largest single source was a few per cent of the whole. Reddit had 2.2% in Google's AI Overviews, and Wikipedia 7.8% in ChatGPT (Profound).
The shares also move: Reddit's share of ChatGPT's citations fell from 3.8% to 0.5% in a few weeks of August 2026 (Semrush). There's no single source to win, only a spread of independent ones to be present in. Paying to be shown doesn't count: AI shopping agents mark down "sponsored" tags.
How to tell it is failing
AI answers name you, then hedge: "some users report", "reviews are mixed".
AI answers quote an old price, a wrong policy or a product you no longer sell.
Ask a machine where its view of you came from, and it names sources that never mention you, or only your own site.
On the platform your buyers actually use, you have fewer than five recent reviews. Or you have a perfect 5.0, which looks managed.
Your proof page shows logos with no names, numbers or dates.
The same number differs between your website, your sales deck and your listings.
Salespeople are asked for references only after the shortlist is set.
The method: a claim, proof and source inventory
The tool for this stage lists everything you claim, with what supports each claim. It takes an afternoon to start and a quarter to fill.
List every claim. Take them from your site, sales deck, listings and ads; most businesses find twenty to forty. Ask legal for the substantiation file they already hold.
Mark each as a fact or a judgement. If a rival would dispute it, it's a judgement.
Make every fact consistent. One wording, one owner, everywhere. Ask several AI assistants, your own chatbot included, about your price, terms and policies, and compare with your one truth from Chapter 10. Where they differ, fix the source the machine read, not the answer.
Give every judgement its proof. Attach the evidence you own: a named customer, a measured result and the date it was true.
Count the confirmations. For each judgement, count the independent sources that say the same thing. My working rule is that a judgement needs at least two, of different kinds, such as a review platform and the trade press. Score each from 0 to 3 using the table below, and take a point off for any live contradiction.
Cut, or earn. A judgement scoring 0 is a slogan. Cut it, or make it next quarter's brief for reviews and press. Or turn it into a fact you can prove: "trusted" becomes "300 cafés, 94% still with us after a year".
Find the machine's sources. Ask the buying questions for your category and read the sources the answers cite. That list is where your confirmations need to live.
Score
What it means
0
Only you say it
1
One independent source says it
2
Two or more independent sources, of different kinds
3
As 2, and AI answers repeat it while citing those sources
The scoring is my own working rule, not tested against sales. Use it to rank the work, not to report to a board.
Admit the weakness, with the fix
By 2009 people said Domino's pizza tasted bad. After about eighteen months reworking the recipe, it ran ads showing its own focus groups calling the crust "like cardboard" and the sauce "like ketchup".
In the first quarter of 2010, sales at its established US stores rose 14.3% on a year earlier (Domino's). The company credited "a remarkably better pizza, and our honesty in how we told consumers about it". That's one quarter, against a weak year, as reported by the company itself.
The order matters. The product changed first, and the admission made the fix believable. In a considered purchase, a flaw admitted without a fix is just a flaw. Admit it with the fix, and with evidence that the fix works.
Reviews, done properly
Reviews are the cheapest confirmation most businesses can earn.
Ask when the job is done. At delivery or completion, while the detail is fresh.
Get from none to five first. That step moves purchase likelihood most.
Show that reviewers bought. Verified buyers lifted purchase likelihood by 15%.
Never filter, and never steer. Fashion Nova paid US$4.2 million to settle a US Federal Trade Commission case over holding back reviews below four stars (FTC). Ask every customer the same way, happy or not.
Let the average be human. Somewhere between 4.2 and 4.7 is more believable than 5.0. Answer the bad reviews in public, and fix what they name.
The bookkeeper's inventory
The bookkeeper for cafés is invented. She has four claims on her home page.
Claim
Kind
Her proof
Who else says it
Score
Action
Your wage cost against takings, every Monday by nine
Fact
The report itself, with a sample on the site
Not needed
n/a
Same wording on the site, the listing and the proposal
Café clients cut wage cost as a share of takings
Judgement
One café's twelve months of numbers
Nobody yet
0
Publish the case with the owner named, then ask two clients to say it in their own reviews
Certified adviser for her accounting software
Fact
Her certification
The software's own partner directory
n/a
Link to the directory from the site
Fast and friendly
Judgement
None
Three Google reviews from 2024
1
Cut the words. Ask every client at the end of their first quarter, until there are five recent reviews
Two of her four claims needed no outside voice, only the same wording everywhere. The other two were requests to be believed, and only one had anything behind it. Her quarter's work is one named case, five reviews and one listing, all of it evidence someone else can check.
Fieldline's inventory
At Northgate, the invented contractor, Mei's objection has dropped. Ravi, the finance lead, now checks the number the whole case rests on: travel time.
Fieldline's figure comes from one customer's 2023 pilot. The website says 20%, the sales deck 18%. Its review-site profile, written by a former product manager, says 25%, and the AI assistant repeats the 25%, citing it.
No machine flagged the contradiction. One version simply won. Ravi set the three figures side by side and asked which was true. The deal paused for three weeks while Fieldline found the pilot data.
Fieldline fixed the source, not the answer.
One number, everywhere. The pilot result, with its date and how it was measured, on the website, in the deck and on every listing. The review-site profile was corrected at the source.
A second voice. The pilot customer's operations manager agreed to be named, and to take reference calls.
Proof for each person. In a committee, a claim that convinces operations does nothing for IT. Mei got a security report. Ravi got a return-on-investment case checked by a customer's finance lead. Dana got peers in the trade forum.
Asked again, the assistant gave the one number and cited the pilot.
By mode
Habitual buyers believe their own last experience, so belief there is won or lost at Kept. Quick choosers read the star rating, the count and the first few reviews: build five recent, verified reviews where they buy. Considered personal buyers check reviews, friends and comparison sites. Owners believe other owners and their trade, so one named peer in the same trade goes furthest. Committees need one proof for each role in the buying group.
How Believed connects to the other stages
It needs Answered and one truth. A claim must be on the page before anyone can check it. Facts stay consistent only if they come from one record.
It feeds Preferred. A reason without proof is a slogan. The machine can repeat a reason only when it can find someone else saying it.
Kept feeds it. Every confirmation is written by a customer, a partner or a journalist who had a reason to say it.
What not to do
Don't claim adjectives. "Leading", "trusted" and "award-winning" are judgements with nothing behind them.
Don't filter or fake. In 2017 a journalist used fake reviews to take a restaurant that didn't exist to number one of 18,092 in London on Tripadvisor (CBC). Platforms and AI firms now treat faked evidence as an attack.
Don't let your own chatbot improvise. What it says, you've said.
How you know it worked
The Selectability Score (Part five) asks whether what's said about you is accurate, and backed by others. It checks the AI answers that name you: do the facts match your one truth, is outside support cited, and do the answers agree?
Your own numbers sit beside it:
the number and recency of reviews on the platform your buyers use;
the share of your judgement claims scoring 2 or more;
the number of open contradictions, which should be zero.
This afternoon
ask an AI assistant whether your brand can be trusted, and where it got that. Then ask your price and main policy three times each, and compare with your website.
This quarter
build the inventory, fix every contradiction at its source, and take your three most important judgements to a score of 2.
Toolkit
The contradiction sweep. Run it once a quarter, and after any change to price, terms or policy. It finds the facts the machines get wrong about you, and fixes them where they started.
Where an answer is wrong, the fix is never to argue with the machine. Find the page, listing or profile it read, correct it there, and ask again.
Every template for this stage is in the free Selectability Playbooks at rocmode.com/playbooks.
What we don't know
No study yet links consistency across sources to how often AI recommends a brand, or to sales. The case here rests on the lab evidence about how models handle conflict, and on what buyers do when they check.
The share of AI citations that come from brands' own sites ranges from 1% to 44%, depending on the study and the question. My reconciliation of the two is an interpretation.
The trust figures are from 2015 and 2021, and the review figures from 2017. The direction is well established. The exact sizes may have moved.
Whose evidence this is. Nielsen sells audience measurement. Yext sells listings management, and McKinsey's figure comes from a third-party tool it doesn't describe. Spiegel's review data was supplied by PowerReviews, which sells review software. Profound and Semrush sell AI-visibility tools. Peer-reviewed sources: Eisend and Küster; Ziegler, Diehl and Ruther. The model-conflict studies are preprints, and Luca's study is a Harvard Business School working paper. Domino's figures are its own.